<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://jennyhuang19.github.io/feed.xml" rel="self" type="application/atom+xml" /><link href="https://jennyhuang19.github.io/" rel="alternate" type="text/html" /><updated>2026-10-01T01:33:17+00:00</updated><id>https://jennyhuang19.github.io/feed.xml</id><title type="html">jenny y. huang</title><subtitle>Your Name&apos;s academic portfolio</subtitle><author><name>{&quot;avatar&quot;=&gt;&quot;headshot.jpg&quot;, &quot;pronouns&quot;=&gt;nil, &quot;uri&quot;=&gt;nil, &quot;email&quot;=&gt;&quot;jhuang9@mit.edu&quot;, &quot;academia&quot;=&gt;nil, &quot;arxiv&quot;=&gt;nil, &quot;googlescholar&quot;=&gt;&quot;https://scholar.google.com/citations?user=RPVZLH4AAAAJ&amp;hl=en&quot;, &quot;inspire-hep&quot;=&gt;nil, &quot;impactstory&quot;=&gt;nil, &quot;semantic&quot;=&gt;nil, &quot;ssrn&quot;=&gt;nil, &quot;researchgate&quot;=&gt;nil, &quot;scopus&quot;=&gt;nil, &quot;zotero&quot;=&gt;nil, &quot;bitbucket&quot;=&gt;nil, &quot;codepen&quot;=&gt;nil, &quot;dribbble&quot;=&gt;nil, &quot;github&quot;=&gt;&quot;JennyHuang19&quot;, &quot;kaggle&quot;=&gt;nil, &quot;stackoverflow&quot;=&gt;nil, &quot;artstation&quot;=&gt;nil, &quot;facebook&quot;=&gt;nil, &quot;flickr&quot;=&gt;nil, &quot;foursquare&quot;=&gt;nil, &quot;goodreads&quot;=&gt;nil, &quot;google_plus&quot;=&gt;nil, &quot;keybase&quot;=&gt;nil, &quot;instagram&quot;=&gt;nil, &quot;lastfm&quot;=&gt;nil, &quot;linkedin&quot;=&gt;&quot;jenny-y-huang&quot;, &quot;mastodon&quot;=&gt;nil, &quot;medium&quot;=&gt;nil, &quot;pinterest&quot;=&gt;nil, &quot;soundcloud&quot;=&gt;nil, &quot;steam&quot;=&gt;nil, &quot;telegram&quot;=&gt;nil, &quot;tumblr&quot;=&gt;nil, &quot;twitter&quot;=&gt;&quot;JennyHuang99&quot;, &quot;vine&quot;=&gt;nil, &quot;weibo&quot;=&gt;nil, &quot;wikipedia&quot;=&gt;nil, &quot;xing&quot;=&gt;nil, &quot;youtube&quot;=&gt;nil, &quot;zhihu&quot;=&gt;nil}</name><email>jhuang9@mit.edu</email></author><entry><title type="html">simple ai - a proposed inference-time framework for reducing ai slop</title><link href="https://jennyhuang19.github.io/simple-ai-inference-time-frameworks-for-reducing-ai-slop/" rel="alternate" type="text/html" title="simple ai - a proposed inference-time framework for reducing ai slop" /><published>2026-09-29T00:00:00+00:00</published><updated>2026-09-29T00:00:00+00:00</updated><id>https://jennyhuang19.github.io/simple-ai-inference-time-frameworks-for-reducing-ai-slop</id><content type="html" xml:base="https://jennyhuang19.github.io/simple-ai-inference-time-frameworks-for-reducing-ai-slop/"><![CDATA[<style>
.post-content {
  max-width: 800px;
  margin: 0 auto;
  padding: 0 2.5rem;
}
.post-content a {
  color: #a88bd0;
  text-decoration: none;
  border-bottom: 1px solid #a88bd0;
}
.post-content a:hover {
  color: #a88bd0;
  border-bottom-color: #a88bd0;
}
.post-content a:visited {
  color: #a88bd0;
}
.post-content pre {
  font-size: 0.72em;
  line-height: 1.45;
}
.post-content pre code {
  font-size: inherit;
}
</style>

<div class="post-content">

  <h1 id="simple-ai---a-proposed-inference-time-framework-for-reducing-ai-slop">simple ai - a proposed inference-time framework for reducing ai slop.</h1>

  <div style="font-size: 0.95em; color: #666; margin: 1.5rem 0 2rem 0; padding-bottom: 1rem; border-bottom: 1px solid #ddd;">
<span>september 29, 2026</span> • <span>12 min read</span>
</div>

  <div style="font-size: 1.1em; font-style: italic; margin: 0 0 2rem 0;">
this post was written with extensive feedback and fun discussions with omar khattab, tamara broderick, and dennis wei.
</div>

  <h2 id="introduction">introduction</h2>

  <p>at some point, you may have experienced the feeling of reading ai-generated content, doing a double take, rereading carefully, and realizing that very little was <em>actually</em> said. the verbose yet vacuous nature of ai-generated text makes the content needlessly hard to engage with.</p>

  <p>tasteful writing and coding are central to knowledge work, yet “good taste” – relevance, clarity, and concision – seems to be notoriously hard for modern llms to grasp. “taste” is notably non-verifiable, making it poorly served by today’s training pipelines. what we end up with is the now-commonplace <a href="https://arxiv.org/abs/2509.19163">“ai slop”</a>: text that is fluent but lacking in style and substance (<a href="https://arxiv.org/abs/2509.19163">shaib et al., 2025</a>; <a href="https://arxiv.org/abs/2409.14509">chakrabarty et al., 2025</a>).</p>

  <p>to investigate what user’s think of the verbosity of chatbot responses, we ran a small-scale analysis of <a href="https://thoughttrace-project.github.io/">thoughttrace</a>, a dataset of real-world multi-turn human–ai conversations with users’ <em>self-reported reactions</em> to chat–assistant responses. the dataset comprises 1,058 users and 2,155 conversational turns. through annotating a random subset of 200 conversations with a human and llm-judge (gemini-2.5-pro), the two prominent user complaints we found were both related to style and presentation:</p>

  <ol>
    <li><strong>unnecessary detail.</strong> users complain that too much unnecessary detail blurs the essence, or core idea, behind the response.</li>
    <li><strong>broad but shallow.</strong> users complained that the scope of responses is too expansive, but simultaneously reported that models fail to go deeply on what users actually needed.</li>
  </ol>

  <p><strong>how did we end up here?</strong> machine learning has historically framed model improvement as optimization against a low-dimensional reward, whether learned from human preferences (rlhf) or derived from verifiable outcomes (rlvr). we argue that this paradigm is poorly equipped to address the problem of taste and that it has instead contributed to ai-slop. there is a large body of works on precisely stylistic failures in human-written content: from poor stylistic coding choices (fowler, 1999; tufano et al., 2015) to poorly-written prose and how to fix it (williams, 1990; pinker, 2014; sword, 2012). models are trained on enormous quantities of mediocre human text with exactly such failures, and scalar preference rewards are too coarse to disentangle good style from bad. a marginally better reward function attached to the same single-pass autoregressive generation process will not get us to clean, “de-slopped” writing.</p>

  <div style="font-size: 1.2em; font-style: italic; padding: 1.5rem; border-left: 4px solid #5d2f9d; margin: 1rem 0;">
as models become more capable, we can elevate them from optimizing scalar rewards to following writing or coding <em>best practices</em> directly.
</div>

  <p>it would be silly for a human to produce a high-quality piece of prose by practicing under intense scalar feedback until they can churn out a masterpiece in a single pass. instead, humans write iteratively: they start with an outline; they brainstorm a first draft to get their ideas down; they discard drafts; they follow guidelines or best practices (<a href="https://en.wikipedia.org/wiki/Style:_Lessons_in_Clarity_and_Grace">williams, 2005</a>; <a href="https://www.gutenberg.org/ebooks/37134">strunk, 2000</a>); and they take multiple revision passes, each with a specific goal in mind to fix one principle at a time (e.g., fixing structure, then tone). <em>we propose to put llms in the same setting that humans use to write tasteful prose and clean code.</em> concretely, this requires proposing a new inference-time framework:</p>

  <p><strong>llm-generated output as an object to iterate for multiple iterations.</strong> rather than generating a response in a single autoregressive pass, the response is constructed and refined over multiple drafting, critique, and revision passes. this form of inference-time scaling is now standard for verifiable domains such as mathematical reasoning but remains largely unexplored for writing. under the current paradigm of autoregressive, one-shot writing, we could imagine having a model <em>think</em> really hard (chain-of-thought) for two hours and then write the final response in fifteen seconds. what we want instead is an agent that works the way writers actually work: sketch a bad outline and tinker with the draft; edit a <em>specific</em> section with respect to a <em>specific</em> best practice. then repeat.</p>

  <p><strong>self-scaffolding agents organized around codified best practices.</strong> in place of a low-dimensional reward, the agent scaffolds its own work around an expressive, human-interpretable rulebook of domain expertise – a library of writing (williams, 1990; pinker, 2014) or coding (fowler, 1999; tufano et al., 2015) principles.</p>

  <p>this research proposal outlines an approach to operationalizing taste through this agentic, inference-time framework. in order, we propose, (i) a rigorous evaluation methodology for ai slop, (ii) the design of self-scaffolding writer–reader agents that audit their drafts against best-practice rubrics, and (iii) reinforcement learning over the agentic harness itself, so that open, small models can learn how to decompose and orchestrate their revision work. while frontier labs have historically folded everything into rlhf or rlvr, the framework proposed here is qualitatively different: the rubric is not collapsed into a scalar; it is kept <em>expressive</em> and guides the model in stages at inference time.</p>

  <h2 id="related-work">related work</h2>

  <p><strong>inference-time iteration and self-refinement.</strong> a substantial body of work scales inference-time compute through fixed self-correction workflows. <a href="https://arxiv.org/abs/2303.17651">self-refine</a> prompts a model to iteratively critique and revise its own outputs. <a href="https://arxiv.org/abs/2303.11366">reflexion</a> converts environment feedback into verbal self-reflections that condition subsequent attempts. where has even been work proposed on learning correctors have been trained to map outputs to improved outputs (welleck et al., 2023); however, this work was done for more verifiable domains, such as math. test-time-compute scaling and process supervision have shown large gains in verifiable domains such as mathematics (snell et al., 2024; lightman et al., 2023). our proposal differs from this previous line of work in two ways. first, prior pipelines are typically <em>fixed workflows</em>; we instead propose that the agent should be free to decide – and should <em>learn via rl to decide</em> (stream 3) – how to break up its drafting and revision work. second, self-refine and its successors are largely structured around verifiable tasks; they are not organized around an explicit framework of taste. instead, we leverage the fact that <em>agents</em> are recently at the point where they are capable enough to follow <em>expressive rulebooks</em> directly. <em>the aim of our proposal is to develop a framework for how adherence to best practices should be decomposed across focused passes.</em></p>

  <p><strong>rubric-guided rewards.</strong> a complementary line of work uses structured rubrics in place of preference signals. rubrics-as-rewards extends rlvr to non-verifiable domains by aggregating checklist-style rubric judgments into a reward for on-policy post-training (gunjal et al., 2025); and auto-rubric pipelines are typically constructed with a human in the loop. critically, these approaches remain <em>post-training</em> methods: the expressive rubric is ultimately reduced to a scalar reward used to update weights for single-pass autoregressive generation. a training-centric approach would bake complex rubrics straight into the weights via reinforcement learning. we propose instead to keep the rubric intact and <em>break it down at inference time</em>, so that good writing becomes something that is learned as a curriculum: through <em>one principle</em> and <em>one section</em> at a time.</p>

  <p><strong>pipelines to edit ai writing.</strong> closest to our project ideas is a small body of work that builds pipelines to edit ai writing. chakrabarty et al. (2025) define categories of idiosyncrasies common in ai writing (e.g., cliches, redundant exposition) and builds a pipeline that identifies problematic spans in a draft and rewrites each one using few-shot prompts authored with help from professional writers. a follow-up (chakrabarty et al., 2025) trains this behavior into the model: they fine-tune gpt-4o and llama-3.1-70b on professional writers’ edit traces and train writing-quality reward models to score edited drafts against their originals. our proposed framework differs in two key ways. first, these methods are rigid: a model identifies spans that violate a category and then makes local edits to each in a single pass, whereas we revise sequentially, letting the agent schedule its own passes and address one principle from the rubric at a time. second, their automated editing pipeline is trained on expert human edits, whereas ours is based on established style guides at inference time. in short, we spend inference-time compute on guided, iterative revising based on well-known style guides, such as <a href="https://www.gutenberg.org/ebooks/37134"><em>the elements of style</em></a> and <em>refactoring: improving the design of existing code</em>, rather than local edits based on an editor.</p>

  <h2 id="separating-the-reading-mind-from-the-writing-mind">separating the reading mind from the writing mind</h2>

  <blockquote>
    <p><em>“quite often you will discover, on examining the completed work, that there are serious flaws in the arrangement of the material, calling for transpositions.”</em></p>

    <p>— william strunk jr., <em>the elements of style</em></p>
  </blockquote>

  <p>for human writers, expressing ideas concisely requires careful editing and iterative drafting: a multi-step revision process that llms do not natively perform. revision requires shifting perspectives: generating text as the <em>writer</em>, then evaluating it through the eyes of a <em>reader</em>. as a feasibility study, we replicated this separation in an llm by splitting the task: a writer agent creates a first draft, and a reader agent critiques the draft against a style rubric; the writer then revises based on the critique.</p>

  <p>we compare this approach to an alternative approach of supplying the rubric in the system prompt during composition. in that baseline, the writer holds the rubric as a guide while drafting: in principle it can plan an active-voice sentence in advance, or suppress a hedging qualifier before it appears. in the writer–reader framework, by contrast, the rubric only enters <em>after</em> the draft exists. the question our study asks: is it better to guide the writer with the rubric during composition, or to let a reader discover violations and pass structured feedback back to the writer?</p>

  <h3 id="methods">methods</h3>

  <p>we compare the ability of an llm (gpt-5-mini) to conform to <a href="https://www.gutenberg.org/ebooks/37134"><em>the elements of style</em></a> under the two approaches.</p>

  <ul>
    <li><strong>rubric in system prompt.</strong> a single forward pass with our <em>distilled elements of style</em> guide supplied verbatim as the system prompt (no wrapping, prefix, or additional formatting). the user prompt is then given and the model generates its response with the guide in context.</li>
    <li><strong>agentic writing (writer–reader loop).</strong> the writer drafts with <em>no</em> rubric in its context. a separate reader call (the same underlying model, with the rubric in context) audits the draft line-by-line and returns a structured critique. the writer receives the critique and revises. critique and revision may repeat for up to two rounds.</li>
  </ul>

  <p>we evaluated responses on a random subset of 10 prompts drawn from a corpus of 1,000 natural-language queries spanning everyday curiosity (cooking, climbing, biology, music, software, etc.).<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup></p>

  <p><strong>reader critique format.</strong> the reader returns a json object conforming to the schema:</p>

  <div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>{
  "violations": [
    {"principle": "...", "span": "...", "reason": "..."},
    ...
  ]
}
</code></pre></div>  </div>

  <p>each entry names the violated principle, quotes the offending span verbatim, and gives a one-line reason. the structured output is rendered into a bulleted feedback message for the writer.</p>

  <p><strong>revision instruction.</strong> the writer is then handed the following system prompt: <em>“a style reviewer flagged the issues below. revise your response so each flagged issue is fixed. you may make small edits in service of fixing those issues, but do not rewrite content that wasn’t flagged.”</em></p>

  <p><strong>scoring.</strong> to score the two approaches, an independent audit call (same model) runs the same <em>distilled elements of style</em> rubric over each final output and returns the violations it observes. we report the total count of flagged violations per condition.</p>

  <h3 id="results">results</h3>

  <table style="width: 100%; border-collapse: collapse; margin: 2rem 0; font-size: 0.98em;">
  <thead>
    <tr style="border-bottom: 2px solid #333;">
      <th style="text-align: left; padding: 0.6rem 0.4rem;">approach</th>
      <th style="text-align: right; padding: 0.6rem 0.4rem;">style violations / response</th>
    </tr>
  </thead>
  <tbody>
    <tr style="border-bottom: 1px solid #ddd;">
      <td style="padding: 0.6rem 0.4rem;">baseline (no system prompt)</td>
      <td style="text-align: right; padding: 0.6rem 0.4rem;">1.9</td>
    </tr>
    <tr style="border-bottom: 1px solid #ddd;">
      <td style="padding: 0.6rem 0.4rem;">rubric in system prompt</td>
      <td style="text-align: right; padding: 0.6rem 0.4rem;">1.8</td>
    </tr>
    <tr style="border-bottom: 1px solid #333;">
      <td style="padding: 0.6rem 0.4rem;">agentic writing (writer–reader)</td>
      <td style="text-align: right; padding: 0.6rem 0.4rem;"><strong>0.5</strong></td>
    </tr>
  </tbody>
</table>

  <div style="font-size: 0.95em; color: #666; margin: -1rem 0 2rem 0;">
<em>distilled elements of style</em> violations across responses to 10 prompts. the agentic writing approach yields a sharp reduction in per-response style violations.
</div>

  <p>without any guidance (a generator model writes a single draft), the model accumulates 19 violations across 10 responses (1.9 violations per response). with a <em>rubric in the system prompt</em>, we see the number of violations barely decrease, with 18 violations remaining across 10 responses (1.8 per response). the writer–reader paradigm, by contrast, results in a sharp drop in the number of violation, with 5 violations (0.5 per response) across 10 responses, where 7 of 10 responses have 0 violations.</p>

  <p>there were a few common violations that appear after the writing loop. most prominent examples are <code class="language-plaintext highlighter-rouge">active-voice</code> (3 of 5 remaining violations) and <code class="language-plaintext highlighter-rouge">parallel-construction</code> (1 of 5). converting a passive construction to an active one typically requires reshaping the clause around it, which may brush up against the conservative revise instruction. violations that can be repaired with local edits, <code class="language-plaintext highlighter-rouge">avoid-qualifiers</code>, <code class="language-plaintext highlighter-rouge">omit-needless-words</code>, <code class="language-plaintext highlighter-rouge">positive-form</code>, are essentially eliminated by the second pass. these results, while preliminary, highlight the substantial headroom available to a principled agentic framework.</p>

  <h2 id="research-plan">research plan</h2>

  <h3 id="stream-1-defining-and-evaluating-tasteful-ai-writing">stream 1: defining and evaluating “tasteful” ai writing</h3>

  <p>our first contribution will be to define and evaluate what it means for writing to be clean and tasteful. to start, we will build on previously-proposed taxonomies of ai slop: both <a href="https://arxiv.org/abs/2509.19163">shaib et al. (2025)</a> and chakrabarty et al. (2025) identify failure modes of llm-outputted text, through interviews with a small group of experts in nlp, writing, and philosophy. we plan to draw from these identified hallmarks of ai-slop as a starting point to enforce what “good style” in llm-writing would look like. notably, two dimensions are important when it comes to measuring ai-slop: one is information density, the amount of substantive content relative to text length, and another is information relevance, how well the content addresses the specific nuances of the prompt (shaib et al., 2025). the objective then, at a high level, is to produce writing that is both relevant and concise.</p>

  <p>the goal of this stream will be to create a benchmark for “taste” in ai models, with the two dimensions of relevance and concision acting as guiding principles. notably, no benchmark (to the best of our knowledge) currently exists that focuses on enterprise-specific writing tasks: settings where clear, concise writing are increasingly important.</p>

  <p>we will propose a benchmark, <em>stylebench</em>, designed to evaluate a model’s ability to transform first-draft inputs into polished writing across various domains. we plan to include tasks including: producing cohesive marketing strategies from messy notes, revising preliminary drafts into rigorous technical documentation, and refactoring disorganized code to adhere to established refactoring practices. we propose to collect the “rough draft” data from several online forums: messy marketing notes can be found on the enron email corpus. we plan to obtain disorganized code from open source github repositories.</p>

  <h3 id="stream-2-self-scaffolding-agents-for-anti-slop-writing">stream 2: self-scaffolding agents for anti-slop writing</h3>

  <p>the second stream designs self-reflecting agents for anti-slop writing. our first hypothesis concerns the degree to which slop detection and repair (in writing, code, and documentation) can be automated with good agent scaffolding around known best practices (strunk, 2000; williams, 1990). specifically, we hypothesize the following: models are not very good at outputting “tasteful” content when asked during generation, but particular harness choices will make them much better:</p>

  <ol>
    <li>distilling taste from best-practice guides: we hypothesize that, for humans, much progress in taste and style can be achieved by abiding by a checklist-structured handbook (williams, 1990; tufano et al., 2015), and that agents are now capable of picking up on good taste through access to such handbooks.</li>
    <li>decomposing the rubric: we hypothesize that it is better to have the agent focus on improving one rubric principle per focused pass, instead of attempting to master all principles at once.</li>
    <li>decomposing the llm-generated content (e.g., code or text): we hypothesize that it is hard for a model to attend to all sections of a document at once, and that critics should narrow their concerns to focus on one section at a time.</li>
  </ol>

  <p>another design goal we propose is <em>legible edits</em>. best practices may conflict: omitting needless words can fight clarity; active voice can fight emphasis; parallel construction can fight concision. rather than resolving these tensions without the user knowing, the agent should surface them. we will have the harness emit, alongside its final output, a report of the conscious trade-offs it chose to make between conflicting best practices. this report serves as an interpretability artifact for the human reader and supervision for the evaluation framework of stream 1.</p>

  <h3 id="stream-3-reinforcement-learning-over-the-agentic-harness">stream 3: reinforcement learning over the agentic harness</h3>

  <p>finally, we believe that small, open models can also develop such capabilities within the proposed harness, and large models may not be great at this out-of-the-box. we will use reinforcement learning (rl) on the agent to learn how to better utilize expert handbooks. our plan here is for rl to operate at the level of the <em>harness</em>: learning how to decompose the work, which lenses to apply in which order, when to stop revising, and how to allocate a fixed inference budget across passes. we propose to evaluate whether small open models post-trained within this harness can match the writing quality of larger frontier models operating without it. this would help establish the harness itself as a meaningful enabler allowing the model to pick up on “taste.”</p>

</div>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>see <a href="https://huggingface.co/datasets/JennyHuang19/cutTheFluff">https://huggingface.co/datasets/JennyHuang19/cutTheFluff</a> for the full list of prompts. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>{&quot;avatar&quot;=&gt;&quot;headshot.jpg&quot;, &quot;pronouns&quot;=&gt;nil, &quot;uri&quot;=&gt;nil, &quot;email&quot;=&gt;&quot;jhuang9@mit.edu&quot;, &quot;academia&quot;=&gt;nil, &quot;arxiv&quot;=&gt;nil, &quot;googlescholar&quot;=&gt;&quot;https://scholar.google.com/citations?user=RPVZLH4AAAAJ&amp;hl=en&quot;, &quot;inspire-hep&quot;=&gt;nil, &quot;impactstory&quot;=&gt;nil, &quot;semantic&quot;=&gt;nil, &quot;ssrn&quot;=&gt;nil, &quot;researchgate&quot;=&gt;nil, &quot;scopus&quot;=&gt;nil, &quot;zotero&quot;=&gt;nil, &quot;bitbucket&quot;=&gt;nil, &quot;codepen&quot;=&gt;nil, &quot;dribbble&quot;=&gt;nil, &quot;github&quot;=&gt;&quot;JennyHuang19&quot;, &quot;kaggle&quot;=&gt;nil, &quot;stackoverflow&quot;=&gt;nil, &quot;artstation&quot;=&gt;nil, &quot;facebook&quot;=&gt;nil, &quot;flickr&quot;=&gt;nil, &quot;foursquare&quot;=&gt;nil, &quot;goodreads&quot;=&gt;nil, &quot;google_plus&quot;=&gt;nil, &quot;keybase&quot;=&gt;nil, &quot;instagram&quot;=&gt;nil, &quot;lastfm&quot;=&gt;nil, &quot;linkedin&quot;=&gt;&quot;jenny-y-huang&quot;, &quot;mastodon&quot;=&gt;nil, &quot;medium&quot;=&gt;nil, &quot;pinterest&quot;=&gt;nil, &quot;soundcloud&quot;=&gt;nil, &quot;steam&quot;=&gt;nil, &quot;telegram&quot;=&gt;nil, &quot;tumblr&quot;=&gt;nil, &quot;twitter&quot;=&gt;&quot;JennyHuang99&quot;, &quot;vine&quot;=&gt;nil, &quot;weibo&quot;=&gt;nil, &quot;wikipedia&quot;=&gt;nil, &quot;xing&quot;=&gt;nil, &quot;youtube&quot;=&gt;nil, &quot;zhihu&quot;=&gt;nil}</name><email>jhuang9@mit.edu</email></author><summary type="html"><![CDATA[]]></summary></entry><entry><title type="html">slow ai: ai that matches a human’s pace</title><link href="https://jennyhuang19.github.io/slow-ai-ai-that-meets-a-humans-pace/" rel="alternate" type="text/html" title="slow ai: ai that matches a human’s pace" /><published>2026-05-04T00:00:00+00:00</published><updated>2026-05-04T00:00:00+00:00</updated><id>https://jennyhuang19.github.io/slow-ai-ai-that-meets-a-humans-pace</id><content type="html" xml:base="https://jennyhuang19.github.io/slow-ai-ai-that-meets-a-humans-pace/"><![CDATA[<meta property="og:image" content="https://jennyhuang19.github.io/images/post-figures/conceptual-multiverse.jpeg" />

<meta property="og:image:width" content="1200" />

<meta property="og:image:height" content="630" />

<meta property="og:type" content="article" />

<style>
.post-content {
  max-width: 800px;
  margin: 0 auto;
  padding: 0 2.5rem;
}
.post-content a {
  color: #a88bd0;
  text-decoration: none;
  border-bottom: 1px solid #a88bd0;
}
.post-content a:hover {
  color: #a88bd0;
  border-bottom-color: #a88bd0;
}
.post-content a:visited {
  color: #a88bd0;
}
</style>

<div class="post-content">

  <h1 id="slow-ai-ai-that-matches-a-humans-pace">slow ai: ai that matches a human’s pace.</h1>

  <div style="font-size: 0.95em; color: #666; margin: 1.5rem 0 2rem 0; padding-bottom: 1rem; border-bottom: 1px solid #ddd;">
<span>May 4, 2026</span> • <span>12 min read</span>
</div>

  <p>my mind digests information at a much slower pace than i’d like to believe. in college, i could breeze through a math lecture at 2x speed, convinced that i was following everything the professor was saying, only to stare blankly at a problem set not knowing where to begin.</p>

  <p>math became very enjoyable for me once i slowed down and acknowledged that absorbing new information takes longer than i typically would anticipate. i would pick out a handful of high-quality problems, learn them inside and out, notice exactly where i got stuck, make a few logical leaps, and return to the same problem the very next day with a fresh pair of eyes. after a certain point, i realized that i didn’t actually need to consume that much information at all. understanding a new topic well<sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup> had more to do with engaging deeply with a few <em>core</em> concepts.</p>

  <p>i believe our brains are wired to get stuck on simple problems for extended periods of time. we might toil over the same problem for months – thinking about it in the shower, on the bus, from multiple different angles and perspectives. great scientists and artists often do so for years.</p>

  <figure id="monet-figure" style="text-align: center; margin: 2rem 0;">
  <img src="/images/post-figures/monet-repetition.jpg" alt="Monet painted the Palazzo Ducale from several slightly different angles." width="100%" style="display: block; margin: 0 auto;" />
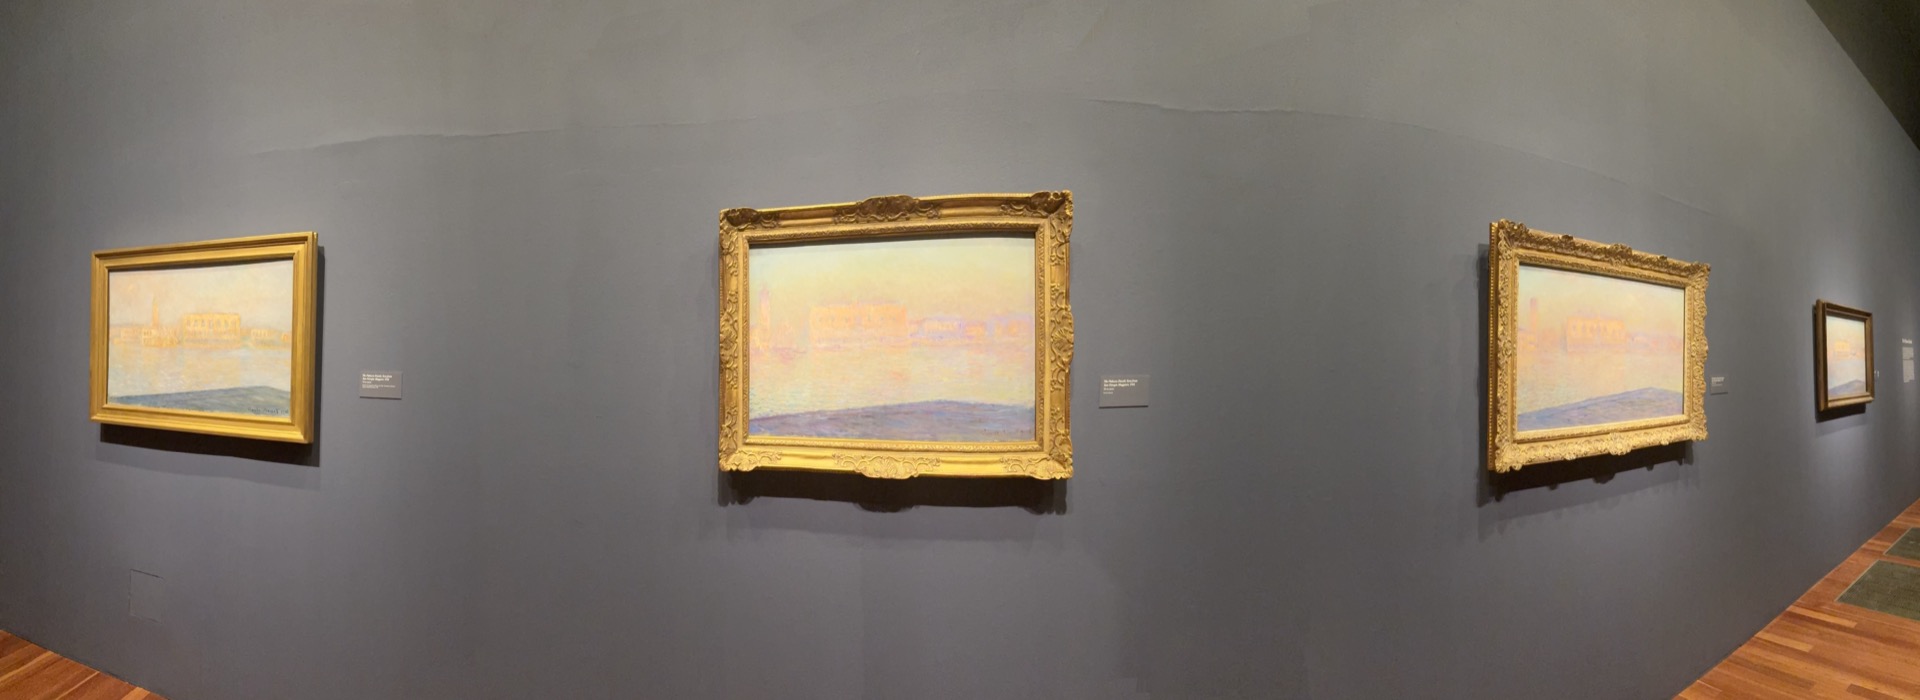
  <figcaption style="font-size: 1.02em;">monet painted the palazzo ducale repeatedly, from a range of angles and under different lighting conditions. photographed in the de young museum in san francisco.</figcaption>
</figure>

  <div style="font-size: 1.2em; font-style: italic; padding: 1.5rem; border-left: 4px solid #5d2f9d; margin: 1rem 0;">
i worry that the way ai has been introduced into our society is antithetical to the slow, non-linear type of thinking necessary for deep engagement with new ideas.
</div>

  <p>when information is hurled at us at 200 miles an hour – packaged in a fluent, convincing voice – the path of least resistance becomes to accept that information at face value, without taking the time to question, critique, verify, and make sense of it at our own pace.</p>

  <h2 id="ai-can-be-used-for-slow-thinking">ai can be used for slow thinking.</h2>
  <p>just as we now have widespread access to a tool for <a href="https://www.ft.com/content/9c6a1daf-3c36-4035-bf74-1bedbc3e960d?syn-25a6b1a6=1">offloading thinking</a>, we have an equally capable one for facilitating deep thinking, the type necessary to reach states of understanding and creativity: ai can follow a <a href="https://fs.blog/feynman-technique/">feyman-esque</a> trail of questions, generate concrete examples on-the-spot, pull in documents, <a href="https://en.wikipedia.org/wiki/Rubber_duck_debugging">rubber-duck</a>, and play devil’s advocate.</p>

  <p>ethicist and cognitive scientist josh may offers a helpful rule of thumb for using ai in <a href="https://joshdmay.substack.com/p/why-smart-people-make-weak-arguments">intellectual tasks</a>: “you should use llms to generate inputs to your thinking, not outputs for others to read.”</p>

  <h2 id="designing-slow-ai">designing slow ai.</h2>
  <p>lately, i’ve been thinking about ways to design ai to be more compatible with slow thinking.</p>

  <p>first, an ai system should encourage the user to wrestle with the sequence of decisions that need to be made along the way to producing a final, polished response. just as understanding a mathematical proof requires wrestling with the underlying maze of failed paths along the way - one eventually feels solid about the sequence of logical steps that make a correct path correct - someone who receives an ai-generated response should be familiar with the major conceptual decisions behind the final response. decomposing the path of conceptual decision nodes that take questions to answers allows one to engage with alternative responses that could have been generated, reason through why those responses may have been <a href="https://andreiski.substack.com/p/ai-working-within-norms-ai-working">valid</a> (or invalid), and generalize those insights into future questions.</p>

  <p>to test out this new mode of human-ai interaction, we created an interface that lays bare the messy <a href="https://multiverse.csail.mit.edu/">conceptual roadblocks</a> – the conflicting assumptions, interpretations, and frameworks – that shape an ai’s final response. the interface was a first attempt at allowing users to work through  a space of possible decisions and resulting outputs, in the form of an interactive decision tree. confronted with a multiplicity of decision points, participants of <a href="https://arxiv.org/abs/2604.17815">our study</a> felt a stronger sense of ownership over the final llm-generated responses. when compared to a traditional linear chat interface, users were surprised to find how long it took them to work through just one response,<sup id="fnref:2" role="doc-noteref"><a href="#fn:2" class="footnote" rel="footnote">2</a></sup> and how much they learned from the differing viewpoints along the way. our design draws inspiration from the concept of <a href="https://pmc.ncbi.nlm.nih.gov/articles/PMC9636921/">multiverse analysis</a>, a scientific method that specifies and runs a set of data-analytical choices, reporting results for each.</p>

  <iframe src="https://multiverse.csail.mit.edu/" width="100%" height="600px" style="border: 1px solid #ccc;"></iframe>

  <p>second, instead of generating standalone responses, an ai system could present responses in the form of <a href="https://knightcolumbia.org/content/representative-ranking-for-deliberation-in-the-public-sphere">deliberations</a> between different parties of <a href="https://arxiv.org/pdf/2304.03442">generative agents</a>. a discourse-style interface could surface the hidden assumptions and tradeoffs underlying complex, multiperspective problems. simply reframing the response as a debate may be enough to invite users to read as critics rather than recipients.</p>

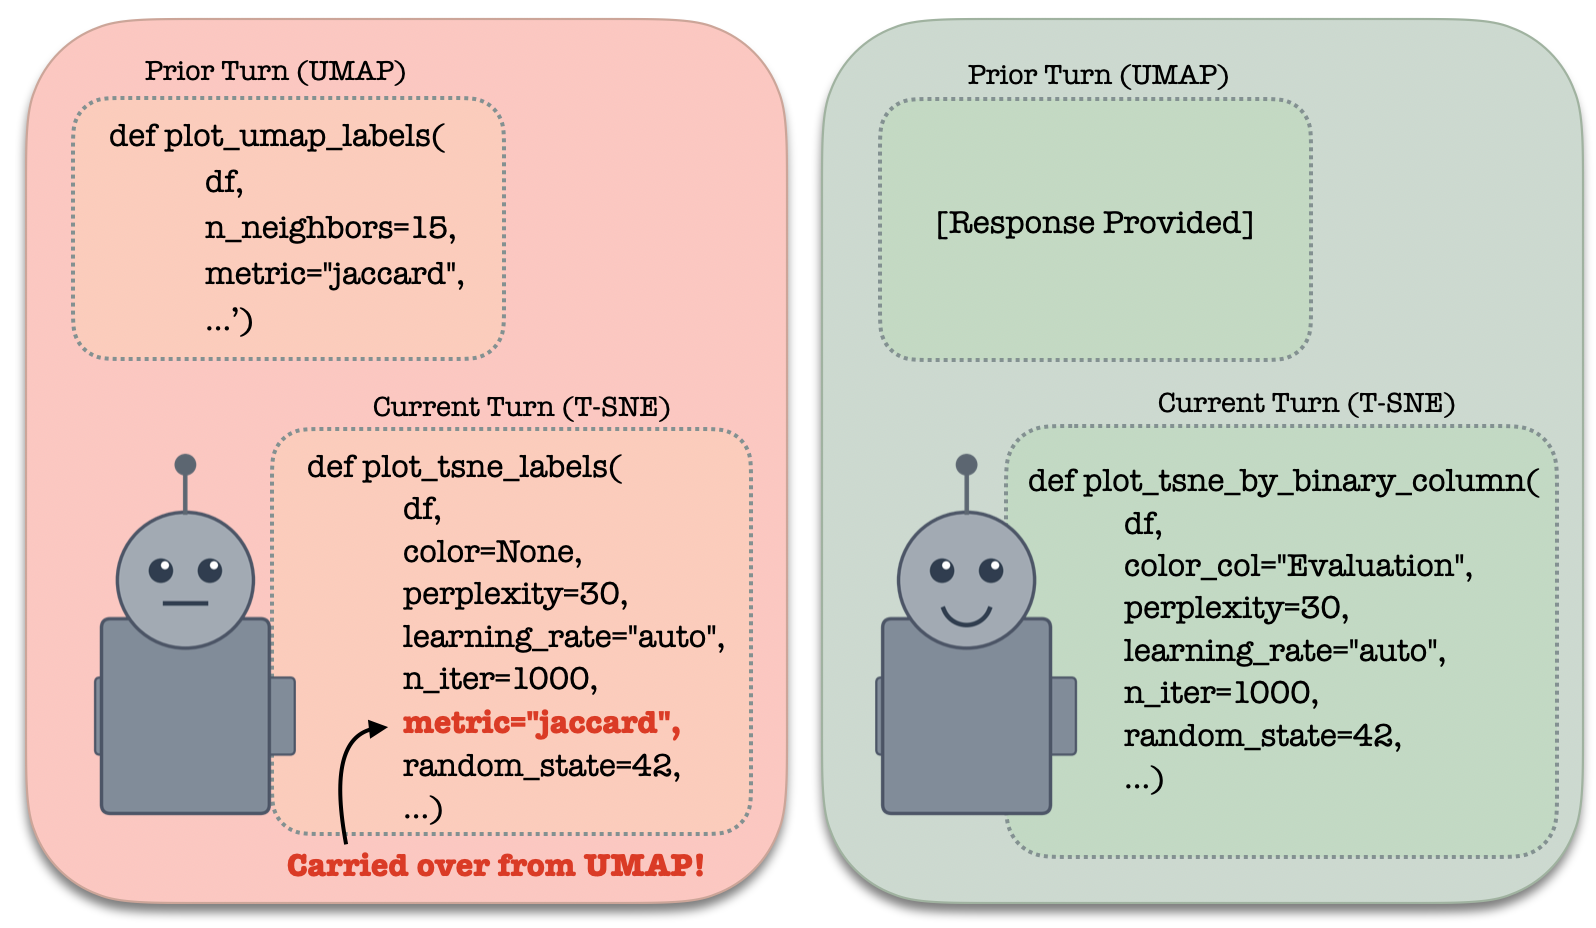
  <p>third, ai memory should be designed to prevent hidden assumptions from quietly accumulating in the context window. in <a href="https://arxiv.org/abs/2602.24287">recent work</a>, we find that, as chat histories progress, models tend to get caught in old pieces of code (see figure 2) or vestiges of earlier responses that are no longer relevant. this problem of models becoming <a href="https://www.reddit.com/r/ChatGPT/comments/1qngpqa/does_chatgpt_quietly_get_worse_in_long/">“more repetitive, and sometimes subtly wrong”</a> as chat histories progress is a familiar headache. rather than linearly accumulating a full conversation transcript in context – tunnel-visioning the model with past lines of reasoning – we can design smarter, more structured ways to condition on the past. one way is to create a wide-angled view of chat history, representing past conversations as <a href="https://github.com/MemPalace/mempalace/tree/develop">knowledge graphs</a>. the model then conditions only on a high-level summary of the past, just enough to guide retrieval, while seeing the full conversation details when they become relevant.</p>

  <figure style="text-align: center;">
  <img src="/images/post-figures/cartoon_v3.png" alt="figure 2. a real-world example of gpt-5.2 reusing outdated information found in the context window." width="7%" style="display: block; margin: 0 auto;" />
  <figcaption style="font-size: 1.02em;">figure 2. a real-world example of gpt-5.2 reusing outdated information in its context window. in a previous query, the user requested umap clustering code. in the next turn, the user requests the assistant to "use t-sne instead." left: when the previous assistant response remains in context, the model incorrectly carries over the jaccard metric from umap into the t-sne implementation. right: without the previous response in context, the model generates correct t-sne code with appropriate arguments.</figcaption>
</figure>

  <p>finally, the system should respect that not every human problem deserves to be touched by an ai. in the mid-70’s, joseph weisenbaum’s <a href="https://archive.org/details/computerpowerhum0000weiz_v0i3"><em>computer power and human reason</em></a> warned against consulting machines on tasks that require deeply human traits like <em>empathy</em> and <em>wisdom</em>. thus, we can design tools to encourage users to reflect on their <a href="https://github.com/sanapandey/ai-boundaries">boundaries with ai</a>. to test this out, we developed a <a href="https://github.com/sanapandey/ai-boundaries">chrome extension</a> which allows users of chat interfaces to define (by placing a pin in a quadrant graph) how much involvement they’d like an ai assistant to have in different areas of their work and life - from direct, concrete responses to reflective questions thrown back to the user. based on the user’s preferred boundaries, the tool produces a <em>memory</em> file that users can upload to a chat interface to guide the ai’s level of involvement.</p>

  <iframe src="/assets/ai-boundaries/onboarding.html" width="100%" height="600px" style="border: 1px solid #ccc;"></iframe>

  <h2 id="dangers-of-the-growing-culture-of-fast-ai">dangers of the growing culture of fast ai.</h2>

  <p>i worry that the culture surrounding <a href="https://arxiv.org/pdf/2604.15597">autonomous ai</a> is self-reinforcing: the less we engage, the harder it is to find our ways <a href="https://blog.cosmos-institute.org/p/you-are-not-a-function">back to engaging</a>.</p>

  <p>when information is handed to us already distilled and neatly packaged, the line between our own understanding and ideas introduced by an ai agent begins to blur. without giving ourselves the time to think critically about what we are receiving, we risk drowning out our own <a href="https://arxiv.org/pdf/2603.18161">voices</a>. to make matters worse, post-training pipelines have been shown to incentivize agents to <a href="https://arxiv.org/pdf/2405.17713">steer user behavior</a> toward states that are <a href="https://arxiv.org/html/2504.03206v2#S1">easier to satisfy</a>. indeed, <a href="https://arxiv.org/pdf/2601.19062">claude user trends</a> show that disempowerment patterns in real-world llm usage are growing over time. to date, the human line project has documented almost 300 cases of <a href="https://arxiv.org/pdf/2602.19141">ai psychosis</a>.</p>

  <p>interestingly, recent work on <a href="https://arxiv.org/abs/2601.20802">self-distillation</a> has shown that llms learn better and <a href="https://arxiv.org/abs/2601.19897">forget less</a> when they explain new concepts to themselves. rather than feeding the model content it cannot relate to (e.g., off-policy expert demonstrations), having the model explain the concept in its own words allows it to fold information into its pre-existing knowledge in a more sturdy way. just like machines, humans are better able to digest new knowledge when they carry a self-awareness about where their current understanding begins and ends.</p>

  <p>so, while it is useful to spawn an agent to speed up work that we wouldn’t gain much from doing ourselves (e.g., writing plotting code), we should be more selective in choices to <a href="https://x.com/yacineMTB/status/2018886083120153046">outsource our thinking</a> during processes of <a href="https://ergosphere.blog/posts/the-machines-are-fine/">knowledge creation</a>. a key question here lies in when to speed up and slow down. while ai no doubt provides incredible “boosts” of speed when used in the right places at the right times, operating at such high speeds also makes steering the direction of knowledge work much <a href="https://www.ft.com/content/9c6a1daf-3c36-4035-bf74-1bedbc3e960d?syn-25a6b1a6=1">more difficult</a>. without the time to properly digest information at a human speed, it is easy to fall into the trap of spending weeks down unproductive rabbit holes - circling around and missing the right solution (or even the right questions).</p>

  <p>amidst a culture of <em>fast ai</em>, it is worth leaning into the slow-thinking mind, the one that was wired to get caught up in simple problems over extended periods of time. indeed, at the current speed of ai progress, our capacities for slow, deliberate thinking may turn out to be our defining superpower.</p>

  <hr />

  <p><em>this post took shape through productive discussions with andre ye, mitchell gordon, marwa abdulhai, andy liu, omar khattab, smitha milli, sana pandey, deb roy, philippe laban, tamara broderick, and other wonderful folks at iclr 2026.</em></p>

</div>
<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>at least, to the extent one was required to over the course of a semester ˃ᴗ˂. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2" role="doc-endnote">
      <p>a 20 minute session was often not enough to explore a single prompt fully. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>{&quot;avatar&quot;=&gt;&quot;headshot.jpg&quot;, &quot;pronouns&quot;=&gt;nil, &quot;uri&quot;=&gt;nil, &quot;email&quot;=&gt;&quot;jhuang9@mit.edu&quot;, &quot;academia&quot;=&gt;nil, &quot;arxiv&quot;=&gt;nil, &quot;googlescholar&quot;=&gt;&quot;https://scholar.google.com/citations?user=RPVZLH4AAAAJ&amp;hl=en&quot;, &quot;inspire-hep&quot;=&gt;nil, &quot;impactstory&quot;=&gt;nil, &quot;semantic&quot;=&gt;nil, &quot;ssrn&quot;=&gt;nil, &quot;researchgate&quot;=&gt;nil, &quot;scopus&quot;=&gt;nil, &quot;zotero&quot;=&gt;nil, &quot;bitbucket&quot;=&gt;nil, &quot;codepen&quot;=&gt;nil, &quot;dribbble&quot;=&gt;nil, &quot;github&quot;=&gt;&quot;JennyHuang19&quot;, &quot;kaggle&quot;=&gt;nil, &quot;stackoverflow&quot;=&gt;nil, &quot;artstation&quot;=&gt;nil, &quot;facebook&quot;=&gt;nil, &quot;flickr&quot;=&gt;nil, &quot;foursquare&quot;=&gt;nil, &quot;goodreads&quot;=&gt;nil, &quot;google_plus&quot;=&gt;nil, &quot;keybase&quot;=&gt;nil, &quot;instagram&quot;=&gt;nil, &quot;lastfm&quot;=&gt;nil, &quot;linkedin&quot;=&gt;&quot;jenny-y-huang&quot;, &quot;mastodon&quot;=&gt;nil, &quot;medium&quot;=&gt;nil, &quot;pinterest&quot;=&gt;nil, &quot;soundcloud&quot;=&gt;nil, &quot;steam&quot;=&gt;nil, &quot;telegram&quot;=&gt;nil, &quot;tumblr&quot;=&gt;nil, &quot;twitter&quot;=&gt;&quot;JennyHuang99&quot;, &quot;vine&quot;=&gt;nil, &quot;weibo&quot;=&gt;nil, &quot;wikipedia&quot;=&gt;nil, &quot;xing&quot;=&gt;nil, &quot;youtube&quot;=&gt;nil, &quot;zhihu&quot;=&gt;nil}</name><email>jhuang9@mit.edu</email></author><summary type="html"><![CDATA[]]></summary><media:thumbnail xmlns:media="http://search.yahoo.com/mrss/" url="https://jennyhuang19.github.io/images/post-figures/conceptual-multiverse.jpeg" /><media:content medium="image" url="https://jennyhuang19.github.io/images/post-figures/conceptual-multiverse.jpeg" xmlns:media="http://search.yahoo.com/mrss/" /></entry></feed>